Let’s explore how you can adopt CI/CD to improve your organization’s efficiency and delivery pipeline in Harness.
TL;DR
- Start with a reliable foundation. Your application should use version control, support frequent code integration, and build successfully from the command line before you automate it.
- Automate validation on every change. A CI pipeline should build the application, run tests, and provide clear pass-or-fail feedback before code is merged.
- Keep feedback fast and trustworthy. Slow builds and flaky tests reduce developer confidence. Selective testing, caching, and parallel execution can help.
- Build security into the workflow. Dependency scanning, security checks, and policy gates help teams catch risks before changes move downstream.
- Measure more than pipeline success. Build duration and failure rates reveal CI performance, while DORA metrics help teams understand broader software delivery outcomes.
- Prepare for AI-generated code. As developers and coding agents produce more changes, CI must validate more code without turning testing and review into bottlenecks.
Continuous integration (CI) is one of the most effective ways to catch software defects early, reduce manual work, and make code changes easier to deliver. But implementing CI involves more than connecting a repository to a build server. A successful CI process brings code, builds, automated tests, and quality checks into a repeatable workflow that runs whenever developers make changes. This guide walks through how to implement continuous integration in eight steps, from preparing your codebase to measuring pipeline performance. You'll also learn how to build a basic CI pipeline in Harness and how to adapt your approach as AI-generated code increases development activity.
How do you implement continuous integration?
To implement continuous integration, put your application in version control, integrate small changes frequently, and automate a repeatable build. Add unit and integration tests, define the workflow as pipeline code, and trigger it for every pull request. Keep results fast and visible, publish versioned artifacts, enforce security checks, and track failures and delivery performance so the pipeline improves over time.
What do you need before implementing continuous integration?
Before creating a CI pipeline, make sure your team has the basic development practices in place.
Continuous integration prerequisites checklist
- Version control: Your application code is stored in a shared Git repository, such as GitHub, GitLab, Bitbucket, or Harness Code Repository.
- Frequent integration: Developers make small changes and merge them regularly, ideally using trunk-based development practices rather than maintaining long-lived branches.
- An automated test suite: At minimum, the application has unit tests that can run without manual intervention.
- A command-line build: A developer can clone the repository, install dependencies, and build the application using documented commands.
- A CI execution environment: You have access to a hosted CI service or self-managed build infrastructure.
- Clear ownership: A team is responsible for maintaining the pipeline and fixing failures.
For example, a Node.js application might already support:
npm ci
npm run build
npm test
These commands should work consistently on a clean machine, not just on a developer's laptop.
If the application cannot be built or tested reliably outside CI, automating those commands will only make existing problems more visible.
For a deeper explanation of the underlying concepts, see What Is Continuous Integration?.
How to implement continuous integration in 8 steps
The following eight steps provide a practical framework for setting up a CI pipeline. You can start with a single application and expand the approach across repositories and teams.
Continuous integration implementation checklist
Step 1: Centralize your code in version control
Continuous integration begins with a shared codebase.
Store your application in a Git repository and establish a consistent approach for submitting and merging changes. Developers should work in small increments rather than accumulating weeks of changes on separate branches.
Long-lived branches make integration harder because codebases diverge. When developers finally merge those changes, they may discover conflicts, incompatible dependencies, or failures that are difficult to trace back to a single change.
A practical starting point is to:
- Choose a shared repository and primary branch, such as main.
- Require pull requests for changes to protected branches.
- Encourage small, frequently merged changes.
- Establish a process for reviewing and resolving failed checks.
How to verify: Create a small pull request, have it reviewed, and merge it through the agreed workflow.
Step 2: Automate the build process
Next, make sure the application builds the same way every time. The build process may compile source code, install dependencies, generate static assets, or package the application into a container image. Whatever the application requires, the process should be scripted and repeatable.
For a Node.js application, a basic build process might be:
npm ci
npm run build
For a Java application using Maven:
mvn clean packageAvoid build processes that depend on files, environment variables, or manually installed tools that exist only on one developer's machine. Use lockfiles and explicit tool versions where practical to reduce differences between environments.
How to verify: Clone the repository into a clean environment and execute the build commands. The application should build successfully without any undocumented steps.
Step 3: Add automated tests to every change
Once the build is repeatable, add tests that verify whether each change behaves as expected.
Start with unit tests because they are generally fast and can catch problems close to the code that introduced them. Add integration tests for important interactions between components, APIs, databases, or services.
A basic test command might look like:
npm testYour CI pipeline should treat a failed test as a failed execution. It should also show which test failed so developers can diagnose the problem without searching through unrelated logs.
As the test suite grows, distinguish between:
- Unit tests: Validate individual functions, classes, or components.
- Integration tests: Validate interactions between services or dependencies.
- End-to-end tests: Validate important workflows from a user or system perspective.
Not every category needs to run in the same way or at the same frequency. The goal is to give developers reliable feedback early while ensuring that critical behaviors are adequately tested.
How to verify: Introduce a deliberately failing test in a temporary branch. Confirm that the pipeline reports the failure and does not produce a successful result.
Step 4: Define your CI pipeline as code
With your build and test commands ready, define the workflow in a CI platform.
A CI pipeline specifies which steps run, in what order, and under which conditions. A typical first pipeline checks out the source code, installs dependencies, builds the application, and runs tests.
Storing the pipeline definition as YAML in version control makes it easier to review changes, reproduce execution, and maintain consistent workflows across teams.
In Harness CI, a pipeline can contain a CI stage with one or more steps. Each step runs a defined command or operation.
A simple sequence looks like this:
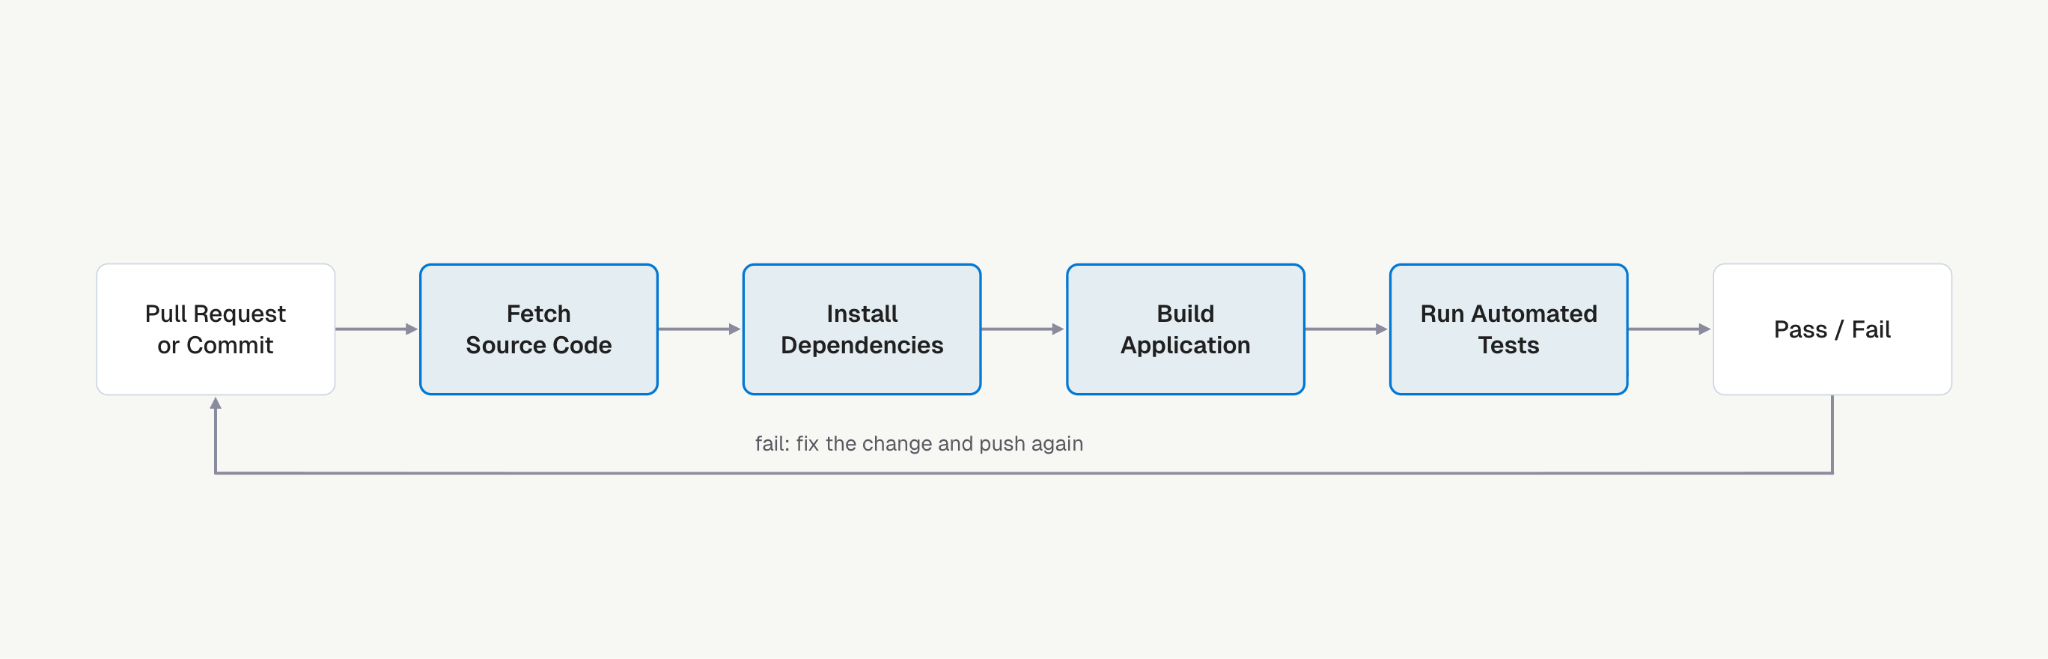
Connect the pipeline to your repository or software factory and configure triggers for pull requests or commits. Then configure the repository's required status checks so changes cannot merge when mandatory validation fails.
How to verify: Push a small change and confirm that the expected pipeline runs automatically, reports its status, and appears in the pull request.
Step 5: Keep build and test feedback fast
A CI pipeline is only useful when developers trust it and receive results soon enough to act on them.
If every minor change triggers a lengthy build and a large test suite, developers spend more time waiting for feedback. As change volume increases, these delays compound.
Several techniques help reduce unnecessary execution:
- Cache dependencies and build outputs. Reuse work that has not changed instead of downloading dependencies or rebuilding everything for every execution.
- Run independent tasks in parallel. Tests and build activities that do not depend on one another can run simultaneously.
- Use selective test execution. Rather than executing every unit test for every change, identify the tests relevant to the modified code.
- Monitor flaky tests. Tests that inconsistently pass or fail without a corresponding code change create noise and trigger unnecessary reruns.
Harness Test Intelligence identifies relevant unit tests based on code changes for supported languages and frameworks, helping reduce unnecessary test execution while preserving visibility into validation results.
Harness also provides caching and other build optimizations to reduce repetitive work.
How to verify: Measure pipeline duration before and after each optimization. Track whether failures remain actionable and whether developers are receiving feedback sooner.
For a detailed look at optimization techniques, see the CI Pipeline Optimization Guide for Platform Engineering Leaders.
Step 6: Store and version build artifacts
A successful CI pipeline should produce an output that downstream systems can use.
Depending on your application, that output could be a compiled binary, an npm package, a Java archive, a container image, or another deployable artifact.
Instead of rebuilding the same code separately in each environment, publish the successful output to an artifact registry.
For example:
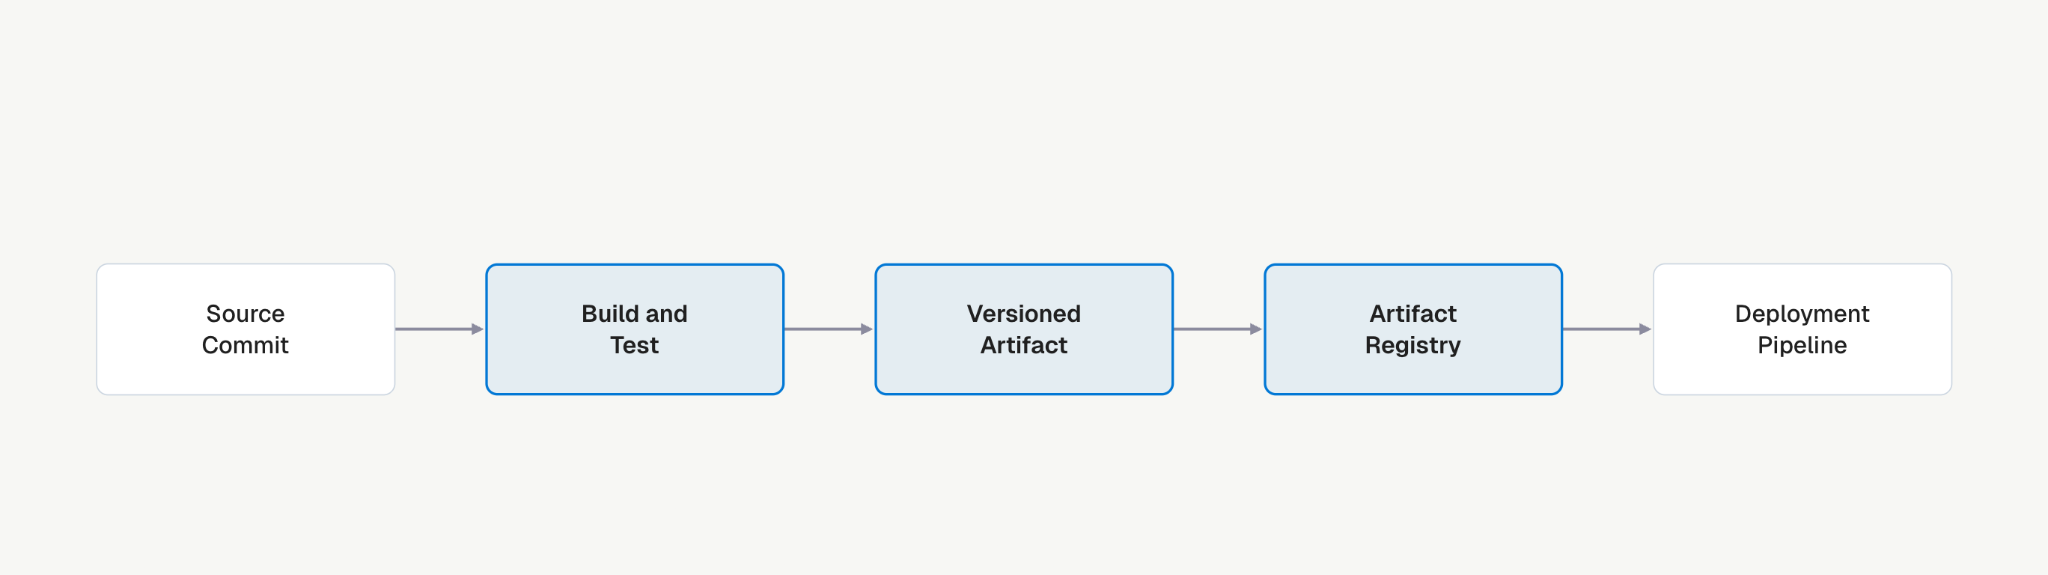
Tag artifacts with a version, commit SHA, or another immutable identifier. This helps teams determine exactly which source revision produced an artifact and makes later deployment or troubleshooting more reliable. Artifact storage should happen only after the required build and test checks succeed.
How to verify: Confirm that the artifact appears in the registry with the expected version or digest and can be retrieved by a separate workflow.
Step 7: Add security scans and policy gates
Continuous integration is also an opportunity to catch security issues before software moves further through the delivery process. Introduce checks appropriate to your application and development environment. These may include:
- Dependency vulnerability scanning
- Static application security testing (SAST)
- Secret detection
- Container image scanning
- Software bill of materials (SBOM) generation
- Policy checks for required pipeline controls
Not every finding should automatically block a build. Define which findings are actionable, which require an exception process, and which should prevent a change from proceeding. For example, a team might initially report lower-severity findings without failing the pipeline, while blocking new critical vulnerabilities according to its security policy. Harness pipelines can incorporate security testing through supported scanners and Harness Security Testing Orchestration. Policy-based governance can enforce configured requirements across pipelines.
How to verify: Test a known policy violation or scanner finding in a controlled branch. Confirm that the pipeline produces the expected result and records the reason for the failure or exception.
Step 8: Measure CI performance and continuously improve
Once CI is running, measure whether it is helping developers deliver changes with less effort and fewer failures.
Begin with a small set of operational metrics:
These metrics help reveal where the pipeline is slowing down or creating unnecessary work.
To understand whether CI improvements translate into broader delivery performance, also track the five DORA software delivery metrics:
- Change lead time: Time from code commit to successful production deployment.
- Deployment frequency: How often changes are deployed.
- Failed deployment recovery time: Time required to recover from a failed deployment.
- Change fail rate: Percentage of deployments that cause failures requiring intervention.
- Deployment rework rate: Percentage of deployments that represent unplanned work to fix production issues.
CI directly contributes to build and validation performance, while DORA metrics help assess outcomes across the larger delivery lifecycle.
How to verify: Establish a baseline, introduce one improvement at a time, and compare results over a meaningful period. A successful change should improve feedback speed or reliability without weakening validation.
Example: Build a simple continuous integration pipeline with Harness
Let's put the steps into practice using a minimal Node.js application.
This example assumes your repository already contains a package.json, a committed lockfile, a working build script, and a test script. The build produces a dist/ directory.
You'll need:
- A Harness account with access to Continuous Integration
- A Harness project and organization
- A Git repository containing your application
- A configured Git connector in Harness
- Access to Harness Cloud build infrastructure
Example Harness CI pipeline YAML
The following pipeline checks out the repository, installs dependencies, builds the application, runs the test suite, and packages the resulting files.
pipeline:
  name: Node CI Example
  identifier: node_ci_example
  projectIdentifier: YOUR_PROJECT
  orgIdentifier: YOUR_ORG

  properties:
    ci:
      codebase:
        connectorRef: YOUR_GIT_CONNECTOR
        repoName: YOUR_REPOSITORY
        build: <+input>

  stages:
    - stage:
        name: Build and Test
        identifier: build_and_test
        type: CI

        spec:
          cloneCodebase: true

          platform:
            os: Linux
            arch: Amd64

          runtime:
            type: Cloud
            spec: {}

          execution:
            steps:
              - step:
                  type: Run
                  name: Install Build and Test
                  identifier: install_build_test

                  spec:
                    shell: Bash
                    image: node:22
                    command: |-
                      set -e
                      npm ci
                      npm run build
                      npm test
                      tar -czf app.tgz dist/
Replace YOUR_PROJECT, YOUR_ORG, YOUR_GIT_CONNECTOR, and YOUR_REPOSITORY with values from your Harness environment.
The commands in this example run in a single Harness Run step. If dependency installation, compilation, or tests fail, the step exits unsuccessfully and the packaging command does not run.
The final command creates an app.tgz file within the build workspace. It does not automatically publish the file to an artifact registry. Add a registry upload or image-publishing step once you have configured the appropriate connector and credentials.
The build: <+input> setting allows the codebase build information to be supplied at runtime. You will also need to configure the appropriate Git trigger to run this pipeline automatically on pull requests or commits.
How to run and verify the pipeline
- Create a CI pipeline in Harness Pipeline Studio and switch to the YAML editor.
- Add the pipeline definition and replace the environment-specific identifiers.
- Connect the pipeline to the repository containing your Node.js application.
- Run the pipeline with the appropriate branch or pull request input.
- Confirm that dependency installation, compilation, and tests complete successfully.
- Introduce a test failure in a temporary branch and confirm that the execution fails.
- Configure a pull request trigger and the required repository status check.
For additional setup instructions, see the Harness CI pipeline creation documentation.
Once the basic workflow succeeds, expand it with test reporting, artifact publication, security checks, and pipeline optimizations.
Common continuous integration mistakes to avoid
Even a working CI pipeline can become a bottleneck if teams overlook reliability and ownership.
1. Builds take too long
The problem: Every change triggers expensive work, even when most dependencies and code have not changed.
What to do: Investigate where execution time is spent. Add dependency caching, parallelize independent work, and consider selective test execution where appropriate.
2. Flaky tests make results unreliable
The problem: A test fails intermittently for reasons unrelated to the code change, leading developers to rerun pipelines or ignore red builds.
What to do: Track flaky tests, investigate shared state and environment dependencies, and quarantine unreliable tests using a managed remediation process. Don't allow quarantine to become a substitute for fixing the tests.
3. Developers rely on long-lived branches
The problem: Changes remain isolated for too long, making conflicts and integration failures harder to resolve.
What to do: Encourage smaller pull requests, frequent integration, and trunk-based development practices. Use feature flags when incomplete features need to remain hidden.
4. Nobody owns the pipeline
The problem: Failed builds remain unresolved because ownership is unclear, dependencies become outdated, and developers create workarounds.
What to do: Establish pipeline ownership, escalation paths, and expectations for fixing a broken primary branch. Treat CI reliability as part of engineering productivity.
For more ways to address these issues, read the CI Pipeline Optimization Guide for Platform Engineering Leaders.
Continuous integration for AI-generated code: Why validation matters more than ever
AI coding tools make it possible for developers and coding agents to generate changes faster. But creating code faster does not automatically mean teams can review, test, and safely deliver it faster.
This increases the importance of continuous integration.
- According to the Harness State of AI in Software Engineering 2025, 72% of organizations reported experiencing at least one production incident directly caused by AI-generated code.
- The validation burden also falls on developers. The State of Engineering Excellence 2026 found that 53% of developers identified reviewing AI-generated code for accuracy as a top source of friction.
These findings highlight a growing imbalance: coding tools can accelerate code creation, while review and testing processes still require considerable time and attention.
What should change in your CI pipeline?
Teams adopting AI coding tools should strengthen the automated feedback surrounding every code change.
- Test every change automatically. Whether code was written by a developer or generated by an agent, it should pass the same required build, test, and security checks.
- Make quality requirements explicit. Define coverage thresholds, required tests, and policy checks so quality does not depend entirely on manual review.
- Keep feedback fast as change volume grows. Use caching, parallel execution, and relevant test selection to avoid repeating unnecessary work.
- Make failures actionable. Developers need to know which change failed, which check was affected, and what needs attention.
- Preserve accountability. Automated review and tests help reduce repetitive validation, but ownership and risk-based human review remain essential.
The objective is not simply to run more tests because more code is being produced. It is to build a validation system that can keep up with development activity while maintaining confidence in each change.
For engineering organizations building AI-powered software factories, CI becomes a critical feedback layer between code generation and software delivery. It determines whether a change is ready to proceed, what needs to be fixed, and whether the resulting software meets the team's quality standards.
Where Harness Continuous Integration fits
Implementing CI becomes more challenging as teams add repositories, increase test coverage, and introduce AI-generated changes. The challenge is no longer just automating builds and tests. It's keeping validation fast, reliable, and manageable at scale.
Harness Continuous Integration provides managed build execution, automated testing, and pipeline governance within the Harness platform.
Several capabilities address the challenges covered in this guide.
Run fewer tests with Test Intelligence
Large test suites can make feedback slower as applications grow.
Harness Test Intelligence analyzes code changes and identifies the relevant unit tests to execute for supported languages and frameworks. This helps teams reduce unnecessary testing while maintaining visibility into test results.
Teams can also use flaky test management and code coverage capabilities to improve the reliability of their quality checks.
The goal is faster feedback without losing confidence in what has been tested.
Reduce repetitive work with build optimization
Repeated dependency downloads and compilation work can consume significant CI time.
Harness provides capabilities such as Cache Intelligence, Build Intelligence, and Docker layer caching to help avoid unnecessary work.
These optimizations are particularly useful when teams are processing more frequent code changes or running multiple builds across large repositories.
Scale builds without managing infrastructure
As CI workloads increase, build infrastructure can become another operational burden.
Harness CI Cloud provides managed build environments so teams can run CI workloads without provisioning and maintaining their own build machines.
This helps platform teams spend less time managing build infrastructure and more time improving developer workflows.
Apply consistent governance across pipelines
As organizations scale, maintaining consistent pipeline standards becomes harder.
Harness supports reusable pipeline templates, access controls, and policy-based governance, helping teams standardize required checks while allowing developers to work within established guardrails.
For AI-assisted development, this means the same validation requirements can apply regardless of how code was created.
Build a faster feedback loop for your software factory
AI coding tools and agents can create more changes, but those changes still need to be built, tested, reviewed, and validated.
Harness CI provides the build and quality feedback that helps determine whether a change is ready for the next stage of delivery. Combined with automated remediation and downstream delivery workflows, that feedback can help teams resolve failures sooner and keep work moving.
Learn more about Harness Continuous Integration and how to accelerate builds, reduce unnecessary testing, and validate code at scale.
Continuous integration establishes the foundation for reliable software delivery: frequent code integration, repeatable builds, automated testing, and trusted artifacts. Once these practices are in place, teams can extend automation into staging and production using continuous delivery. That includes environment management, deployment strategies, approvals, verification, and rollback processes. To explore the next stage, see Harness Code Deployments. The objective here is not automation for its own sake. It's to make every change easier to validate so developers can spend less time waiting, troubleshooting, and repeating manual checks and more time delivering software that works.